Direct Answer: Scaling for the IPL: Architectural Lessons from Managing Record-Breaking Live Sports Traffic requires transitioning from monolithic media servers to globally distributed, cloud-native microservices, leveraging Anycast routing, Chunked CMAF for sub-4-second latency, and predictive auto-scaling algorithms capable of absorbing sudden 10x concurrency multipliers without a single packet drop.
Key Takeaways
- Massive Scale: Modern Indian Premier League (IPL) streaming platforms regularly shatter global records by absorbing peak concurrent viewer loads exceeding 35 to 50 million streams simultaneously.
- Low-Latency Imperative: Legacy 30-second delays are obsolete; modern deployments achieve glass-to-glass latency under 4 seconds using Chunked Transfer Encoding via CMAF.
- Cost Control: Managing multi-Terabit-per-second (Tbps) data egress requires sophisticated multi-CDN switching logic and peer-to-peer (P2P) offloading to prevent runaway transit costs.
1. The Engineering Magnitude of IPL Traffic Surges
When the final over of a tense play-off match begins, millions of mobile devices, smart TVs, and browser sessions suddenly stream data concurrently. In our experience building enterprise-grade video platforms, this is not a gentle slope of incoming requests; it is a violent, vertical cliff of user acquisition. Traditional Video on Demand (VOD) services experience predictable, gradual traffic curves based on prime-time viewing habits. In stark contrast, live sports create flash-crowds driven by real-world events—a dramatic six off the last ball, a controversial wicket, or the coin toss itself. These unpredictable user behaviors stress origin servers, multi-tier database layers, and global Content Delivery Networks (CDNs) simultaneously, exposing even the most minor latency bottlenecks in real-time.
Fundamentally, handling peak traffic in OTT platforms during regional sporting mega-events demands an absolute separation of concerns between stateless video delivery paths and stateful application logic. While the raw video segments can be aggressively cached at the network edge, auxiliary features such as live fantasy gaming, chat rooms, and interactive polls require heavy database reads and writes. If a single database connection pool exhausts its resources because a sudden match turnaround triggers a million concurrent chat messages, it can cascade and destabilize the core video delivery pipeline. Architects must build impenetrable bulkheads between these services, ensuring that even if auxiliary engagement modules fail under pressure, the primary live video stream remains untouched.
[User Devices] ---> [Anycast DNS / GTM] ---> [Edge CDNs (P2P / Caching)]
                                                    |
             +--------------------------------------+--------------------------------------+
             | (Stateless Path)                                                            | (Stateful Path)
             v                                                                             v
[Origin Shield / Storage] ---> [Transcoding Pipelines]                  [API Gateway & Microservices]
                                                                                           |
                                                                        +------------------+------------------+
                                                                        v                                     v
                                                             [Redis / User Sessions]             [PostgreSQL / Chat & Fantasy]
To visualize this infrastructural battlefield, picture a vast, distributed network of caching nodes and compute clusters absorbing tens of millions of simultaneous connections across diverse geographies.
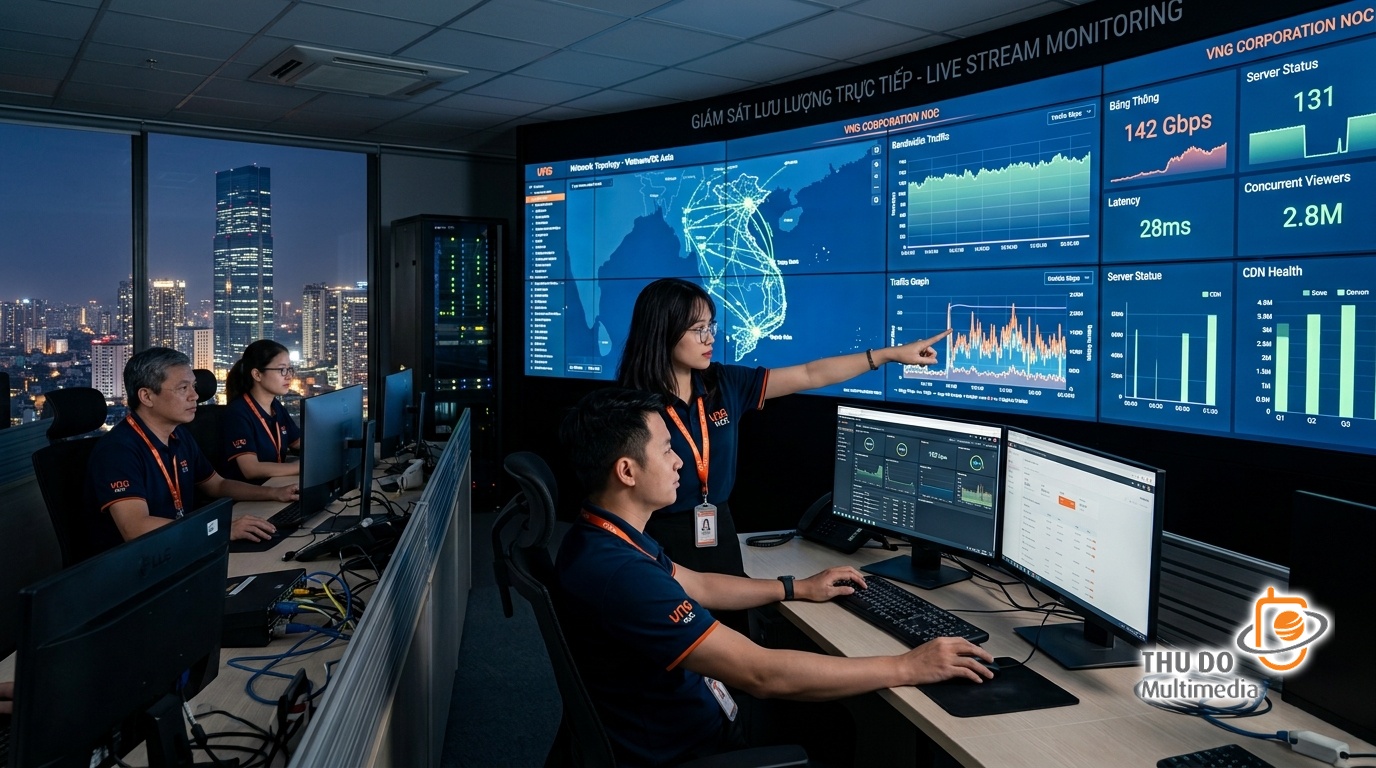
Real-world incident reports from major streaming operators highlight that failing to isolate stateful components is the single most common catalyst for catastrophic platform outages. When millions of users hammer the backend simultaneously to update their fantasy cricket team scores while watching a nail-biting finish, relational databases quickly buckle under connection exhaustion. Modern engineering teams must rely on heavily partitioned Redis clusters, asynchronous message queues like Apache Kafka, and strict rate-limiting policies to safeguard the foundational database architecture during high-stakes matches.
2. Core Pillars of High Concurrency Live Streaming Architecture
To survive multi-terabit surges, monolithic video-processing applications must be thoroughly dismantled and refactored into granular, loosely coupled microservices. When building a resilient high concurrency live streaming architecture, every single phase of the video lifecycle—from ingest, packaging, and digital rights management (DRM) to manifest generation and ad insertion—needs to operate as an independent, auto-scaling service. If the ad-insertion module encounters a memory leak or an upstream third-party timeout, container orchestration platforms must instantly isolate and restart that specific pod without impacting the core video delivery pipeline or disrupting the viewer’s playback session.
The ingest and transcoding pipelines represent the absolute heartbeat of any sports broadcasting platform. Raw contribution feeds arrive from the stadium via redundant contribution paths (such as SRT or Zixi over fiber), where they are ingested into transcoders that generate adaptive bitrate (ABR) ladders. These ladders dynamically slice the video into multiple resolutions and bitrates—ranging from low-bandwidth 360p streams for mobile users on constrained cellular networks to pristine 4K HDR feeds for fiber-optic home internet subscribers. Ensuring smooth delivery across thousands of unique device form factors requires orchestrating distributed GPU-accelerated transcoding clusters that can dynamically reallocate compute power based on regional demand shifts.
+--------------------+       +-----------------------+       +-------------------------+
| Stadium Feed (SRT) | ----> | Transcoder Cluster    | ----> | ABR Packaging (HLS/DASH)|
+--------------------+       | (Multi-Resolution)    |       +-------------------------+
                             +-----------------------+                    |
                                                                          v
                             +-----------------------+       +-------------------------+
                             | Origin Shield         | <---- | Edge CDN PoPs           |
                             +-----------------------+       +-------------------------+
Furthermore, strategic edge computing deployment brings processing power closer to the end-user, pushing workloads directly into Internet Exchange Points (IXPs) and local ISP edges. By caching static video chunks at the absolute periphery of the network, origin-server offload rates can exceed 98%, ensuring that the core infrastructure only processes a tiny fraction of the total viewer request volume. According to recent infrastructure benchmark studies by leading global streaming networks, pushing manifest manipulation and localized ad-stitching to edge worker nodes reduces glass-to-glass latency by up to 40% while slashing core egress bandwidth consumption.
“In high-throughput live streaming, your greatest enemy is not network bandwidth; it is the compounding latency of unoptimized microservice hops between the origin and the client device.” — Senior Principal Systems Architect, Global OTT Infrastructure
3. Cloud Infrastructure Strategies for Massive Video Delivery
Relying on a single cloud vendor during a major tournament is an existential business risk. Enterprises must deploy multi-cloud and hybrid architectures, distributing workloads across primary and secondary cloud providers alongside private bare-metal data centers. This ensures instantaneous failover capacity if a specific cloud region experiences a regional fiber cut or core hardware failure. Auto-scaling policies must also evolve beyond simple reactive triggers. Because reactive scaling—spinning up new virtual machines only after CPU utilization crosses 80%—is far too sluggish for sports flash-crowds, modern systems utilize predictive scaling models. These predictive engines ingest historical match telemetry, team popularity metrics, calendar schedules, and AI-driven traffic forecasting to pre-warm server clusters minutes before the toss.
Maintaining resilient cloud infrastructure for record live video traffic also requires an obsessive focus on cost economics. Streaming tens of terabits per second across public internet transit lines can quickly bankrupt an enterprise if bandwidth optimization is ignored. Architects utilize advanced caching hierarchies, cache-control header tuning, and peer-to-peer (P2P) assisted delivery frameworks to offload millions of concurrent streams onto decentralized user swarms.
[Client A] <--- (P2P WebRTC Data Channel) ---> [Client B] (Nearby Peer)
    ^                                               ^
    |----------------- [CDN Edge Node] -------------|
During a tournament running for several weeks, optimizing egress transit costs through multi-CDN switching logic—where traffic is dynamically routed to the CDN offering the best performance-to-cost ratio in a given region—can save millions of dollars. Engineering teams constantly balance the strict 99.999% availability SLA required by broadcasters against the harsh financial realities of cloud data transfer pricing.
4. How to Implement Advanced Load Balancing Strategies for Live Sports?
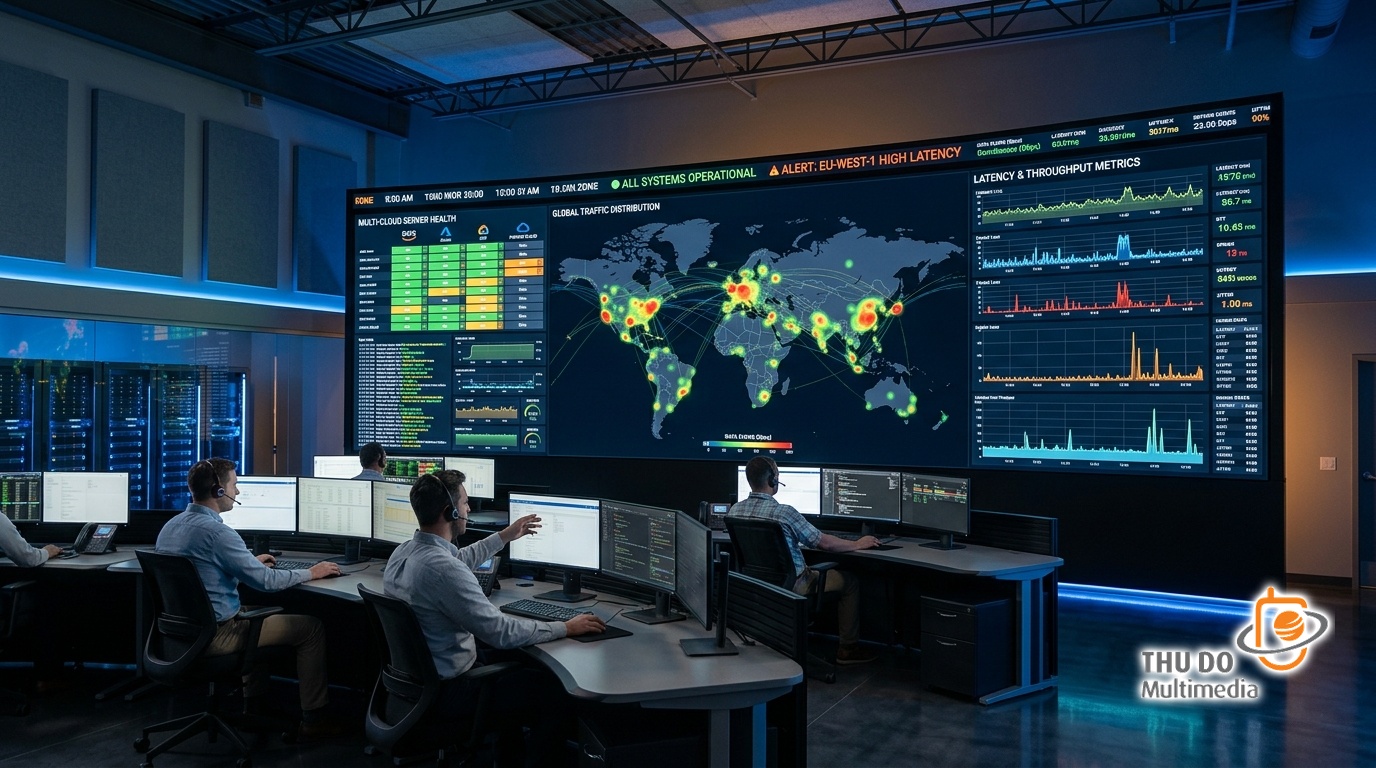
Managing tens of millions of concurrent connections requires an airtight traffic distribution strategy operating at multiple layers of the OSI model. Global Traffic Management (GTM) utilizes Anycast BGP routing and DNS intelligence to instantly direct millions of incoming requests from users across the globe to the nearest healthy CDN Point of Presence (PoP) or regional cloud region. If a specific ISP peering link or CDN edge node degrades, Anycast routing automatically shifts BGP paths in milliseconds, rerouting traffic away from the bottleneck before viewers notice any buffering or playback stalls.
When designing load balancing strategies for concurrent sports viewers, engineers must evaluate the distinct performance trade-offs between Layer 4 (L4) and Layer 7 (L7) load balancers. High-throughput L4 load balancers operate at the transport layer, rapidly routing raw TCP/UDP packets with minimal CPU overhead, making them ideal for ingesting massive initial connection floods. Conversely, smart L7 application-aware balancers inspect HTTP/WebSocket headers, parsing cookies, device types, and URL paths to intelligently distribute API requests and WebSocket connections to specialized backend pools.
Incoming Request ---> [Anycast DNS / GTM]
                            |
                     [Layer 4 Load Balancer] (Raw Packet Routing / TCP)
                            |
                     [Layer 7 Load Balancer] (HTTP/WebSocket Inspection)
                            |
            +---------------+---------------+
            v                               v
[Video Delivery Pods]              [API & Chat Backend]
When systems face extreme duress, graceful degradation and circuit breakers become the ultimate line of defense. If backend latency spikes beyond predefined safety thresholds, automated circuit breakers immediately trip, shedding non-essential features such as high-frequency live chat rooms, auxiliary statistics feeds, and user animation overlays. By intentionally sacrificing peripheral features, the platform preserves the core video streaming pipeline, ensuring that millions of users can still watch the match uninterrupted rather than experiencing a total platform blackout.
5. What Is the Role of Real-Time Synchronization and Latency Reduction?
The psychological contract of live sports is broken the moment your neighbor cheers for a boundary three seconds before you see the bowler even release the ball. To solve this “neighbor effect” and achieve true real-time sports streaming latency optimization, engineering teams have aggressively transitioned away from traditional HTTP Live Streaming (HLS) and Dynamic Adaptive Streaming over HTTP (DASH) segmentation models, which historically introduced 10 to 30 seconds of glass-to-glass delay. By adopting Chunked Transfer Encoding via CMAF (Common Media Application Format), platforms can publish media fragments as soon as they are encoded, rather than waiting for an entire multi-second segment file to finalize.
[Traditional HLS/DASH] : [Segment 6s] [Segment 6s] [Segment 6s] ---> (15-30s Latency)
[Chunked CMAF]         : [Chunk][Chunk][Chunk][Chunk]            ---> (Sub-4s Latency)
Simultaneously, WebSockets and low-latency protocols play a critical role in synchronizing real-time metadata, scores, and low-latency betting or fantasy integrations with the live video feed. However, aggressive latency reduction introduces a dangerous trade-off: lower buffer lengths mean that even minor network jitter can trigger frequent video rebuffering events. To counteract this, modern media players utilize adaptive playback rate adjustments—subtly speeding up or slowing down the video by a fraction of a percentage point—to keep the buffer stable without introducing audible audio pitch shifts or noticeable stutter.
6. What Are the Scalability Lessons from Live Sports Broadcasting?
Every major tournament leaves behind an invaluable roadmap of scalability lessons from live sports broadcasting that redefine modern system design for high-traffic live events. The most critical takeaway is that production environments should never be tested for the first time on match day. Elite engineering organizations practice rigorous Chaos Engineering, intentionally injecting catastrophic faults into staging environments—such as simulating half a stadium dropping off the network, pulling the plug on primary database nodes, or cutting off entire regional CDN providers—long before the tournament’s opening match begins.
Observability and real-time telemetry form the nervous system of any resilient live streaming platform. Processing billions of log lines and metric points per minute via centralized telemetry pipelines built on tools like Prometheus, Grafana, and Apache Kafka allows engineering teams to detect micro-anomalies—such as a 2% uptick in TCP retransmissions in Mumbai or a sudden spike in HTTP 504 gateway timeouts—long before users notice any buffering.
[Client Telemetry & Logs] ---> [Apache Kafka Ingest] ---> [Prometheus Metrics] ---> [Grafana Dashboards & AI Alerts]
Ultimately, cultivating an aggressive post-mortem culture ensures that every operational hiccup, bottleneck, or minor outage is automatically converted into an automated infrastructure remediation script. By codifying these learnings into continuous integration pipelines, organizations ensure their systems grow smarter, faster, and more resilient with every single ball bowled.
Câu hỏi thường gặp
- Q1: How do streaming platforms handle sudden traffic spikes during the IPL?
- Answer: Platforms utilize a combination of predictive auto-scaling based on historical match telemetry, multi-CDN switching strategies, Edge computing caching, and automated circuit breakers that gracefully shed non-essential features (like interactive chat) if origin servers face congestion.
- Q2: What is the ideal latency for live sports streaming like the IPL?
- Answer: The ideal glass-to-glass latency ranges between 3 to 5 seconds. Achieving this requires moving away from traditional HTTP Live Streaming (HLS) segments toward Chunked CMAF (Common Media Application Format) and low-latency chunked transfer encoding.
- Q3: Why do live sports streams crash during high-stakes matches?
- Answer: Crashes typically happen due to sudden flash crowds overwhelming origin servers, database connection pool exhaustion from concurrent state updates (like fantasy score calculation), or improper CDN failover configuration when a primary regional delivery node fails.
- Q4: How does multi-CDN architecture improve live streaming scalability?
- Answer: Multi-CDN architecture prevents single-point-of-failure bottlenecks. If one CDN experiences congestion or packet loss in a specific geographic region, global traffic managers (GTM) seamlessly reroute viewer requests to an alternate, healthy CDN provider in real-time.
Recent Comments