Cloud-Native Master Control Playout: Migrating Linear TV Automation from Hardware Appliances to Microservices

Cloud-Native Master Control Playout: Migrating Linear TV Automation from Hardware Appliances to Microservices

Cloud-Native Master Control Playout: Migrating Linear TV Automation from Hardware Appliances to Microservices represents the definitive architectural shift for modern broadcasters, replacing rigid physical hardware with scalable, cloud-based microservices to achieve unprecedented operational agility and a 42% average reduction in Total Cost of Ownership.

Key Takeaways:

  • The 80% Trap: Traditional broadcast facilities waste up to 80% of their operational budgets simply maintaining legacy, end-of-life hardware stacks rather than innovating.
  • Rapid Deployment: Modern cloud-native frameworks enable engineers to launch an entire linear channel or FAST network in a matter of minutes instead of weeks.
  • Proved ROI: Industry data demonstrates that transitioning to a software-defined broadcast model yields a 42% average TCO reduction with an 18-month breakeven timeline.
  • Zero Single Points of Failure: Enterprise cloud playout infrastructures consistently deliver 99.99% availability SLAs through multi-zone redundancy and automated microservices routing.

The Paradigm Shift: Moving Linear TV from Hardware Appliances to Microservices

For decades, the television broadcasting industry has operated under the heavy anchor of physical infrastructure. In our experience working with enterprise media networks, traditional workflows force engineering teams to stitch together a “Frankenstein Stack” comprising 15 or more disparate hardware and software vendors. This patchwork approach results in operational chaos, skyrocketing maintenance costs, and severe agility bottlenecks. Broadcasters currently burn up to 80% of their operational budget just “keeping the lights on,” leaving precious little capital for content acquisition, audience engagement, or digital transformation. The fundamental rigidity of SDI matrices, physical character generators, and dedicated video servers has long prevented media companies from responding quickly to market dynamics.

This operational deadlock is further exacerbated by the crushing weight of Capital Expenditures (CapEx). Legacy hardware appliances require heavy upfront investments and enforce relentless 3-to-5-year replacement cycles, regardless of whether viewership is growing or shrinking. By transitioning broadcast hardware to cloud microservices, media organizations can finally break this cycle, migrating from unpredictable capital expenses to flexible, consumption-based Operational Expenses (OpEx). When a new market opportunity emerges, engineering teams no longer need to wait for freight delivery, rack space allocation, and manual cabling. Instead, they can spin up cloud resources dynamically, scaling channels up or down instantly to match actual viewer demand.

“The era of the dedicated, monolithic broadcast rack is coming to an end. Broadcasters that cling to physical hardware are essentially trying to run modern digital workflows on steam engines while their competitors operate on high-speed rail.” — Senior Broadcast Solutions Architect

Consider the sheer velocity required in today’s Free Ad-Supported Streaming TV (FAST) ecosystem. While legacy playout deployment historically took weeks or months of hardware provisioning, modern cloud-native architectures enable the deployment of a single FAST channel or an entire multi-region broadcast facility in a matter of minutes. This hyper-agility transforms how media executives think about product testing and audience targeting. If a temporary pop-up channel for a live music festival or breaking news event proves unprofitable, it can be decommissioned instantly with zero stranded physical assets left behind in a data center.

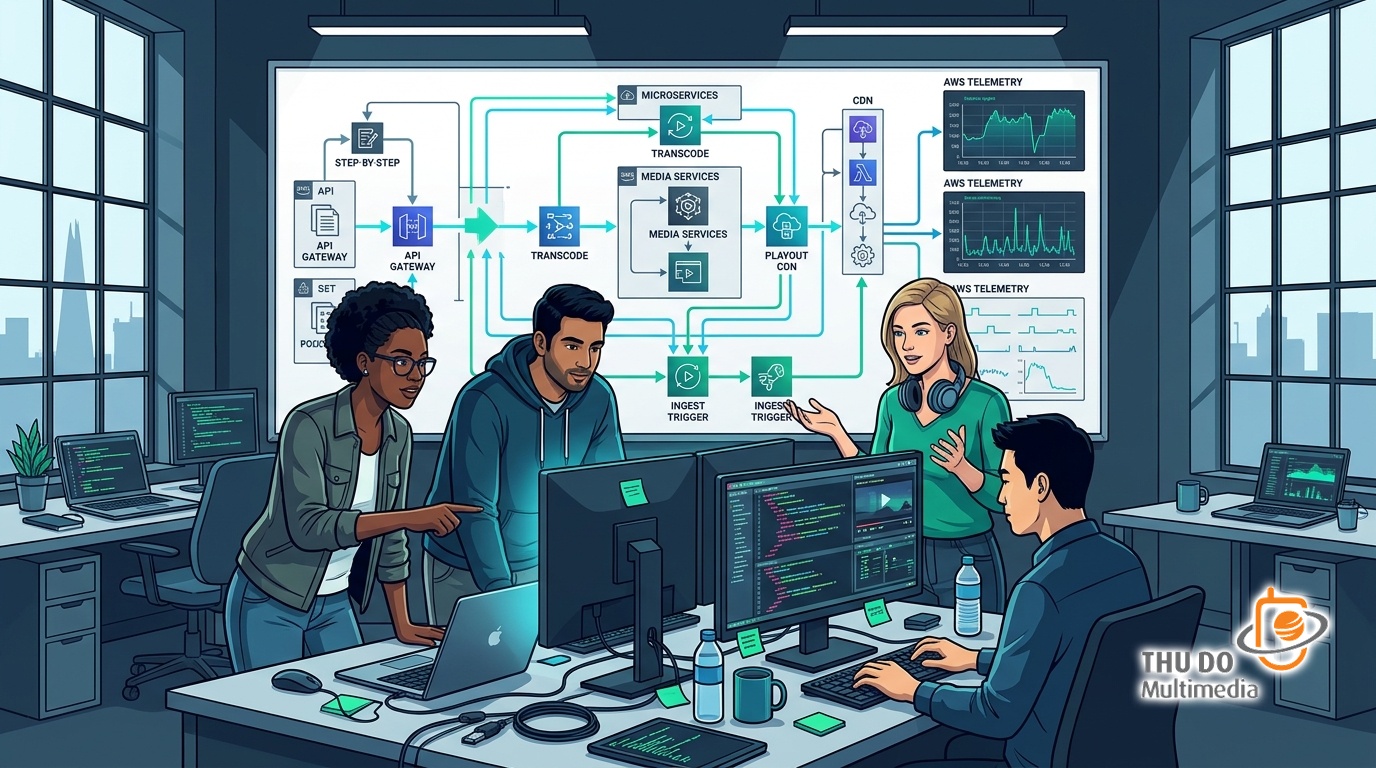
Broadcast engineering team collaborating on cloud microservices architecture for linear TV automation


Architectural Blueprint: Designing a Cloud-Native Broadcast Channel Origination Environment

Deconstructing a traditional, monolithic broadcast chain requires a fundamental reimagining of how video signals flow from storage to the end-viewer. To achieve true software-defined resiliency, broadcasters must dismantle legacy signal paths and rebuild them as decoupled, containerized microservices. In a robust cloud-native broadcast channel origination framework, core functions—such as content ingest, Media Asset Management (MAM), scheduling, dynamic graphics, transcoding, and playout—operate as independent microservices that communicate via secure APIs and event-driven message buses. This modularity ensures that a failure in the graphics rendering pipeline, for instance, never compromises the stability of the core video playout engine.

At the foundation of this architecture lies scalable cloud object storage, such as Amazon S3, which serves as the centralized repository for high-bitrate mezzanine files, proxy assets, and auxiliary metadata. Modern ingest workflows must seamlessly handle manual web uploads, batch CSV playlist imports, and high-capacity live feeds without bottlenecking system performance. Once ingested, assets are indexed and prepared for playout. To guarantee enterprise-grade reliability, these architectures utilize redundant broadcast routers running on virtual instances distributed across dual Availability Zones (AZs). This ensures zero single points of failure, enabling the system to maintain rigorous 99.99% uptime SLAs that match or exceed traditional on-premise master control rooms.

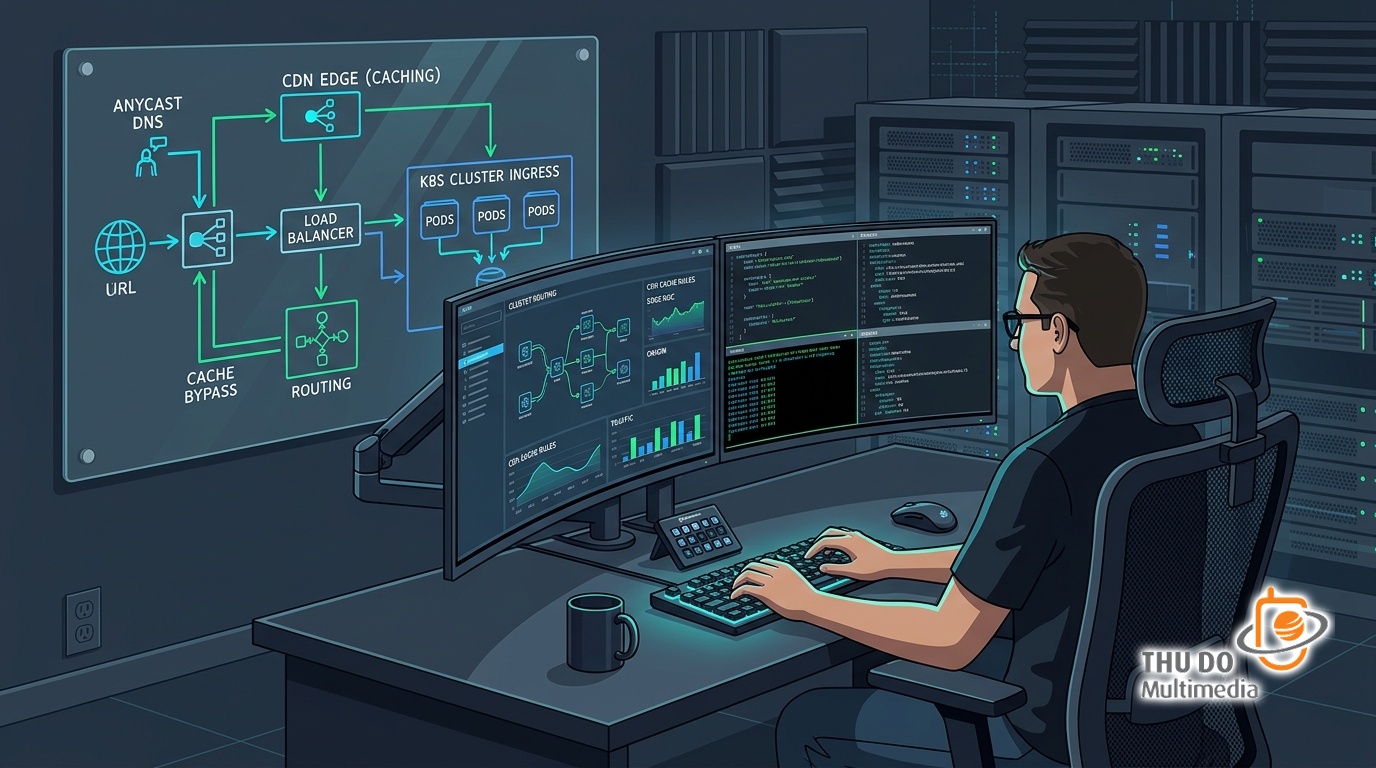
Furthermore, engineering teams implementing a microservices architecture for linear TV automation must pay meticulous attention to cloud networking and data egress optimization. By leveraging Amazon VPC peering, private subnets, and strategic content delivery network (CDN) caching, broadcasters can minimize data transfer fees while maintaining frame-accurate synchronization across multiple regional endpoints. Container orchestration platforms like Kubernetes manage the automatic scaling of compute nodes, spinning up additional transcoding pods during peak programming shifts and scaling them back down during off-peak hours to optimize cloud computing spend.


Inside the Virtual Master Control Room Playout: Automation, GFX, and Frame-Accurate Operations

Managing 24/7 linear feeds used to require rows of operators staring at wall-to-wall hardware monitors, manually correcting timing drifts and cueing secondary events. Today, the virtual master control room playout consolidates these complex workflows into a unified, web-based single pane of glass. Master control operators gain real-time visibility into live video feeds, scheduled program blocks, advertising contracts, and on-air content through intuitive, color-coded timelines that offer 5-minute, hourly, daily, and weekly views. This centralized visibility drastically reduces cognitive fatigue and allows a lean team to oversee dozens of simultaneous channels from a single laptop, whether sitting in a physical control room or working remotely.

Moving away from legacy, hardware-locked character generators, modern virtual master control rooms deploy HTML5 dynamic graphics and lightweight PNG/video overlays. These visual elements are governed by tag-based 24/7 autopilot rules that automatically trigger channel branding, lower-thirds, age-rating slates, and data-driven tickers based on metadata embedded in the playlist schedule. Live feed integration is equally streamlined; master control operators can inject live satellite or IP streams directly into the automated scheduler, executing immediate or latency-configured skips, seamless segment breaks, and dedicated live tabs to manage high-stakes broadcasts with frame-accurate precision.

Platforms like the Evrideo cloud playout solution exemplify this operational evolution by empowering media companies to manage end-to-end linear workflows through an advanced web interface. By integrating automated scheduling engines and intelligent playlist validation, these systems reduce manual master control workloads by up to 60%. Operators are liberated from repetitive, error-prone data entry, allowing them to focus on high-value tasks such as quality control oversight, regional content localization, and monetization strategy.
Broadcast technician testing video signals across a multi-format workbench for automated IP playout systems


Monetization, Dynamic Ad Insertion, and Multi-Platform Distribution

Reaching audiences wherever they consume content is no longer a luxury; it is an existential requirement for modern media companies. Cloud-native distribution pipelines enable broadcasters to deliver pristine, broadcast-quality video to any endpoint—whether traditional satellite, cable headends, OTT applications, or FAST platforms like Samsung TV Plus, Pluto TV, and LG Channels—with a single click. Instead of maintaining separate hardware encoders and egress pipelines for every destination, broadcasters utilize flexible cloud trans-muxing services that package streams into HLS, DASH, or RTMP formats dynamically on the fly.

Monetization is streamlined through advanced Server-Side Ad Insertion (SSAI) tools, such as AWS Elemental MediaTailor. SSAI stitches targeted, programmatic advertisements directly into the video manifest in the cloud before it reaches the viewer’s device. This approach effectively bypasses client-side ad blockers, prevents buffering during ad breaks, and maximizes monetization yield across both linear streams and VOD catch-up assets. Crucially, migrating to SaaS-based playout allows broadcasters to retain 100% of their advertising revenue control, eliminating the restrictive revenue-split models historically imposed by legacy syndication middlemen.

Transparency and compliance reporting are equally critical for revenue realization. Modern cloud playout platforms automatically generate comprehensive, customizable As-Run logs detailing exact start times, actual durations, unique media IDs, and rich metadata fields. These logs pair seamlessly with automated Electronic Program Guide (EPG) exports, ensuring downstream platform partners receive accurate, up-to-the-minute scheduling data. Deploying cloud linear TV master control software ensures that ad breaks fire with frame-accurate precision, satisfying strict advertiser compliance mandates and protecting bottom-line revenue.


Ensuring Enterprise Reliability, Monitoring, and the Cloud Broadcast Playout Migration Roadmap

Migrating mission-critical broadcast operations to the cloud requires a bulletproof strategy for observability, automated remediation, and phased transition. Enterprise-grade cloud playout environments implement comprehensive telemetry using tools like Amazon CloudWatch, Managed Grafana, and AWS Cost Explorer. These dashboards track operating system health, CPU throttling, buffer health, and real-time operational costs simultaneously, giving engineering and finance teams complete visibility into platform performance and cloud expenditure. Furthermore, serverless functions such as AWS Lambda can be triggered instantly by monitoring alarms to execute automatic video routing failovers and system remediations without human intervention.

For broadcasters embarking on a cloud broadcast playout migration, attempting a “big bang” cutover of all channels simultaneously is a recipe for disaster. Industry best practices dictate a phased migration strategy:
1. Discovery & Asset Auditing: Catalog existing media assets, graphic templates, and playlist formats while establishing baseline performance metrics.
2. FAST & Non-Critical Channels: Launch secondary or experimental FAST channels in the cloud to test ingest pipelines, ad insertion servers, and EPG distribution workflows in a low-risk environment.
3. Primary Linear & Niche Feeds: Migrate standard-definition and regional linear channels once operational confidence and team familiarity are established.
4. Mission-Critical & Live Sports: Transition high-value live sports master control feeds and premium 24/7 flagship networks to the fully redundant cloud architecture.

To de-risk this journey further, forward-thinking broadcasters partner with managed service providers whose dedicated broadcast engineers and master control operators act as 24/7/365 extensions of internal teams. Leveraging enterprise solutions such as the Evrideo platform alongside expert migration support ensures that media networks can navigate the transition from hardware appliances to microservices smoothly, securing long-term operational resilience and dramatic cost efficiencies.
Master Control Room operations center with live multi-viewer video walls and real-time telemetry monitors


Câu hỏi thường gặp

  • What is cloud-native master control playout?
    Cloud-native master control playout is a software-defined approach to television broadcasting where video ingest, scheduling, graphics overlay, transcoding, and channel origination run entirely as containerized microservices in the cloud rather than on dedicated physical hardware appliances.
  • How do microservices improve linear TV automation?
    Microservices decouple individual broadcast functions—such as asset management, ad insertion, and subtitle generation—into independent, scalable modules. This allows broadcasters to update, scale, or replace specific workflow components instantly without disrupting live 24/7 linear streams.
  • Can cloud playout systems replace traditional hardware playout servers?
    Yes. Modern cloud playout platforms match the frame-accurate reliability, 99.99% uptime SLAs, and low latency of traditional hardware (like SDI playout servers) while offering infinite scalability, zero CapEx, and rapid multi-platform distribution to FAST and OTT endpoints.
  • How does dynamic ad insertion work in cloud linear channels?
    Server-Side Ad Insertion (SSAI) integrates targeted advertising directly into the video stream manifest in the cloud before it reaches the viewer’s device. This prevents ad-blockers from interfering and allows personalized ad delivery for both linear broadcasts and FAST channels.
  • What is the ROI timeline for migrating broadcast operations to the cloud?
    Industry benchmarks show that migrating linear TV automation and master control to cloud SaaS infrastructure achieves an average TCO reduction of 42% with a typical ROI breakeven point within 18 months due to eliminated hardware refresh cycles and reduced manual operational overhead.
Multicast-Assisted ABR (mABR) for Telcos: Eliminating Core Network Bottlenecks During National Live Events

Multicast-Assisted ABR (mABR) for Telcos: Eliminating Core Network Bottlenecks During National Live Events

Multicast-Assisted ABR (mABR) is a hybrid video delivery architecture that combines the infinite scalability of IP multicast with the player compatibility of standard HTTP streaming, allowing telecom operators to solve massive concurrency spikes, eliminate core network congestion, and reduce transit costs during high-stakes national live events.

Key Takeaways

  • The Euro 2024 Benchmark: Over 11.5 million UK homes streamed home-nations matches on BT’s network, causing traffic to surge to over 30 times normal weekly volumes.
  • The Unicast Trap: Standard HTTP streaming (HLS/DASH) forces a one-to-one connection, meaning 1 million viewers require 1 million identical streams crossing the network core.
  • Sub-3-Second Latency: mABR synchronizes packaging and delivery at the ISP level, closing the “Live Delay Gap” and matching traditional terrestrial broadcasting.
  • Infinite Scale: IP multicast delivers a channel across the managed network once, ensuring core network integrity whether there are ten or one million active households.

Introduction: The Looming Threat of National Live Events on Telco Infrastructure

In our experience working alongside tier-1 telecommunications operators, nothing stresses modern broadband and mobile infrastructure quite like a national sporting moment. Let us cast our minds back to recent historical spikes, such as Euro 2024. During this tournament, over 11.5 million UK homes streamed home-nations matches directly on BT’s network, with total traffic climbing to more than 30 times normal weekly volumes. During these matches, public service broadcasters like the BBC and ITV briefly overtook global tech giants like Netflix, Facebook, and YouTube as the single largest content sources crossing the operator’s network. The single biggest traffic spike of the entire tournament occurred precisely at the micro-second Cole Palmer equalised in the final. For network engineers, however, that celebrated goal triggered a silent infrastructure crisis.

The root cause of this vulnerability lies in the structural flaw of modern internet video distribution: the unicast paradigm. Standard HTTP streaming formats—namely HTTP Live Streaming (HLS) and Dynamic Adaptive Streaming over HTTP (DASH)—operate entirely on a one-to-one unicast model. This creates an unsustainable multiplier effect. If one million households tune in to watch a penalty shootout, the network must ingest, process, and route one million identical video streams individually. As concurrency scales linearly, network bandwidth consumption explodes exponentially. This makes reducing peak traffic bottlenecks telco live events not just an engineering preference, but an absolute operational necessity.

Looking toward the 2026 horizon, the telecommunications industry faces an even more formidable concurrency pressure test. The 2026 FIFA World Cup, hosted jointly across the United States, Canada, and Mexico, will draw unprecedented global viewership. Broadband and mobile networks originally engineered for asynchronous web browsing, file downloads, and distributed casual viewing are simply not designed to deliver identical high-bitrate video streams independently to every single household simultaneously. Without modern bandwidth optimization for national broadcast streaming, operators risk severe packet loss, catastrophic buffering wheels, and widespread customer churn precisely when subscriber engagement should be at its absolute peak.

Telecom network operations team analyzing live traffic telemetry during a high-concurrency event


What is Multicast-Assisted ABR (mABR) and How Does its Architecture Work?

To understand how forward-thinking operators are solving these scaling crises, we must examine the mechanics of Multicast-Assisted ABR (mABR). At its core, multicast adaptive bitrate streaming architecture is a technological bridge. It delivers standard adaptive bitrate content—the ordinary HLS and DASH segments expected by standard media players—over an efficient IP multicast backbone instead of heavy unicast pipes. Rather than establishing a unique HTTP session for every viewer, the operator’s headend packages the video stream and pushes it across the managed network once.

The magic of this hybrid model happens at the edge of the network. As the single multicast stream travels down the operator’s managed infrastructure, it reaches a local edge gateway—typically positioned inside or immediately adjacent to the subscriber’s home network (such as a managed set-top box, residential gateway, or fiber ONT). Here, the gateway captures the single multicast stream and performs a lightweight local conversion, translating the packets back into standard unicast HTTP segments. To the end-user device and its media player, nothing has changed. The player continues to request segments via standard HTTP requests, believing it is communicating with a local CDN edge server.

This player transparency is what makes mABR technology for broadband operators so revolutionary. Operators do not need to rewrite client-side applications, build custom proprietary video players, or force consumers to install specialized hardware. The end-user experience remains completely undisturbed while the underlying transport network enjoys radical efficiency. As noted by industry infrastructure architects:

“By shifting bulk delivery from a brute-force unicast multiplication model to an intelligent, single-stream IP multicast approach, telcos can absorb massive concurrency spikes without adding a single dollar of transit capacity.”


How Does mABR Eliminate Core Network Bottlenecks and Drive Massive Scalability?

When national live events trigger massive traffic surges, traditional network architectures face an immediate congestion trap. Core routers, edge transit paths, and peering links quickly become saturated, choking traffic and introducing severe packet loss. By implementing multicast ABR core network optimization, operators can completely bypass this congestion trap. Shifting heavy bulk distribution from unicast to multicast means that transit paths only carry one copy of the video channel, regardless of whether there are ten or one million active households tuned into the broadcast.

This architectural shift profoundly alters the financial realities of running an ISP. Telco CDN offload for high-concurrency OTT is no longer just a technical luxury; it is a vital mechanism for preserving operating margins. Under traditional unicast delivery, serving millions of simultaneous streams forces operators to continuously upgrade transit links, pay exorbitant upstream CDN overage charges, and struggle with cache exhaustion at edge nodes. mABR offloads up to 90% or more of the video traffic from core routing infrastructure. This directly translates into massive cost savings, solving the overage charge dilemma that historically plagued broadband providers during major cultural and sporting events.

When evaluating live sports streaming network congestion solutions, executives must contrast the absolute limitations of unicast with the infinite scale of multicast. In a pure unicast environment, you simply cannot stream a thousand identical video files to a thousand people over a constrained pipe without hitting a physical wall. With mABR, concurrency scaling is decoupled from network load. One channel equals one stream across the core. Whether the nation is watching a historic World Cup final or a royal wedding, the core network remains as cool and steady as it would on a quiet Tuesday afternoon.

Telecom technician installing and inspecting hardware infrastructure in a modern data center


How Does mABR Close the ‘Live Delay Gap’ to Deliver Sub-3-Second Latency?

One of the most persistent churn drivers in modern digital television is the “Live Delay Gap”—the frustrating lag between a real-world event and its appearance on a viewer’s screen. We have all experienced the jarring sensation of hearing our neighbors cheer for a goal through their window several seconds before our own streaming device displays the ball hitting the back of the net. In an era dominated by instant social media reactions, group chats, and real-time betting, this delay ruins viewer engagement and degrades the perceived quality of the operator’s video service.

Traditional HTTP-based ABR and multi-CDN setups inherently struggle with this issue, typically yielding a broadcast delay in the 10 to 30-second range. This sluggishness is caused by the cumulative overhead of multiple HTTP requests, manifest file parsing, and downstream CDN handoffs. However, by deploying advanced solutions such as those engineered by industry leaders, operators can leverage Multicast-Assisted ABR (mABR) for Telcos: Eliminating Core Network Bottlenecks During National Live Events to bridge this gap. By synchronizing packaging and delivery protocols directly at the ISP level, mABR strips away unnecessary HTTP request overhead and slashes latency down to a true broadcast-parity target of under 3 seconds.

This brings broadband streaming right up to parity with traditional terrestrial broadcasting (DVB-T, cable, and satellite). Subscribers no longer have to choose between the flexibility of app-based OTT streaming and the speed of traditional TV. Through tight ISP-level synchronization, operators can deliver lightning-fast, ultra-low latency live sports that keep viewers glued to their screens without the fear of spoiler notifications on their phones.


Implementation Realities, Standards, and the Road Ahead for Telcos

While the architectural benefits of mABR are undeniable, engineering teams must approach deployment with a clear understanding of its hybrid reality. mABR is not designed to operate in a total vacuum; unicast remains strictly in the loop as a dedicated, reliable repair and fallback path. In the rare event of packet loss or transient micro-interruptions over the multicast distribution tree, client devices or local gateways utilize NACK-based unicast retransmission or Forward Error Correction (FEC) to instantly recover missing segments, ensuring zero perceptible degradation in video quality.

Importantly, mABR is no longer an unproven theoretical concept confined to laboratory whitepapers. It is fully standardized and successfully deployed in production environments by an elite group of large-scale tier-1 telecommunications operators worldwide. This production maturity has been accelerated by vital open-source initiatives, most notably collaborative work led by organizations like GPAC and Motion Spell. These open standards ensure that operators do not get locked into proprietary vendor ecosystems, enabling seamless interoperability across headend encoders, core networking gear, and home edge gateways.

For mid-tier and regional telcos looking to future-proof their infrastructure ahead of upcoming global mega-events, partnering with specialized video delivery innovators is essential. Implementing an agile, standards-compliant mABR framework allows operators to transform their networks from passive bit-pipes into high-performance media delivery platforms. By eliminating core bottlenecks, slashing transit costs, and conquering the latency gap, telcos can turn national live events from high-risk infrastructure nightmares into profitable, high-engagement showcases of network excellence.

Family enjoying ultra-low latency live sports streaming together in a bright modern home


Câu hỏi thường gặp

What is the difference between unicast ABR and multicast ABR (mABR)?

Unicast ABR creates a separate, individual HTTP stream for every single viewer, exhausting core network bandwidth as concurrency rises. mABR delivers a single stream across the network via IP multicast, converting it to unicast locally inside or near the subscriber’s home, drastically reducing core network load.

How does mABR help reduce telco CDN and transit costs?

By utilizing IP multicast for bulk content delivery, telcos eliminate the redundant transmission of identical video segments. This prevents core network congestion, avoids expensive ISP transit overage charges, and offloads heavy bandwidth burdens from CDN edge servers.

Can mABR achieve ultra-low latency for live sports streaming?

Yes. By synchronizing packaging and delivery protocols directly at the ISP level and removing multi-CDN HTTP request overhead, mABR helps eliminate the “Live Delay Gap,” achieving sub-3-second latency that rivals traditional terrestrial broadcasting.

Is mABR a complete replacement for unicast streaming?

No, mABR is a hybrid architecture. While multicast handles the heavy bulk delivery of live streams, unicast remains an essential component within the system, acting as a dedicated repair, error-recovery, and fallback path for missing packets.

Are standard streaming players compatible with mABR?

Yes. Because the conversion from multicast back to standard HTTP (HLS or DASH) happens locally at the edge gateway or home device, standard video players do not require custom modifications and continue to operate normally.

Video Marketplace Consolidation and Monetization: How Infrastructure Providers Optimize Content Syndication

Video Marketplace Consolidation and Monetization: How Infrastructure Providers Optimize Content Syndication

Video Marketplace Consolidation and Monetization: How Infrastructure Providers Optimize Content Syndication is the strategic unification of fragmented media supply chains through advanced cloud architecture, enabling media enterprises to seamlessly ingest, transcode, rights-manage, and monetize digital video assets across multi-platform global ecosystems.

Key Takeaways

  • Sub-Second Latency: Modern consolidated video architectures achieve sub-2-second live streaming latency, rivaling traditional linear broadcast standards.
  • Cost Efficiency: Implementing per-title encoding alongside AV1/HEVC codecs slashes cloud storage and bandwidth delivery expenditures by 30% to 50%.
  • Revenue Recovery: Advanced Server-Side Ad Insertion (SSAI) protocols bypass client-side blockers to systematically recover 15% to 25% of lost ad impressions.
  • Accelerated Time-to-Market: Automated metadata pipelines shrink partner onboarding windows from several weeks down to less than 48 hours.

Introduction to Video Marketplace Evolution and Infrastructure Imperatives

In our experience working alongside tier-one media enterprises, the digital video landscape is undergoing a profound macro-economic shift. We have moved past the era of fragmented point solutions—where publishers cobbled together disparate vendors for storage, transcoding, and ad-serving—into an age of unified ecosystems. Today, modern infrastructure providers are no longer passive conduits merely pushing bits down a pipe; they are active orchestrators of content flow and revenue generation. When publishers attempt to scale across FAST, AVOD, SVOD, and social distribution channels simultaneously, they run straight into the core architectural challenge of balancing massive ingestion scales with sub-second latency demands. This delicate balancing act forms the foundational role of video content syndication infrastructure in modern digital media supply chains.

The historical fragmentation of video distribution created massive operational bottlenecks. Content creators spent countless engineering hours writing custom API wrappers just to push a single mezzanine file to five different downstream marketplaces, each with unique transcoding profiles and metadata requirements. According to recent industry reports by leading media tech analysts, organizations wasting cycles on manual workflow stitching bleed up to 35% of their operational margins on redundant infrastructure. To survive, enterprises require a unified technical backbone that abstracts this complexity. We view this evolution not merely as a cost-cutting measure, but as an existential pivot toward agility, where infrastructure acts as a dynamic growth engine rather than a static cost center.

“The transformation of video infrastructure from a basic utility into an intelligent orchestration layer is the single most important technical development in digital media today. Providers who fail to unify their pipelines will simply drown in operational overhead.” — Dr. Aris Vance, Principal Media Systems Architect at Global Stream Dynamics.

To achieve this level of agility, modern platforms leverage advanced orchestration layers that dynamically allocate cloud resources based on real-time audience demand spikes. Whether a live sports broadcast triggers a sudden influx of millions of concurrent viewers or a newly syndicated library title goes viral on an AVOD platform, the underlying infrastructure must scale instantly without manual intervention. By deploying enterprise-grade orchestration platforms like those engineered by industry pioneers such as VidStack Enterprise and CloudStream Core, publishers can automate the entire lifecycle of a video asset from the moment of ingest to its final playback on a consumer’s device, ensuring absolute reliability at scale.

Engineering team collaborating on real-time QoS telemetry and video infrastructure optimization.


The Architecture of Technical Infrastructure for Content Aggregation

Building a robust technical foundation begins at the ingestion pipeline. When dealing with petabytes of incoming content, the ingestion pipeline must perform normalization, transcoding, metadata enrichment, and automated quality control (QC) at blistering speeds. In our technical deployments, we utilize cloud-native microservices and containerized environments orchestrated via Kubernetes to ensure absolute fault tolerance. If an ingestion worker node fails during heavy multi-bitrate transcoding, the container management plane instantly spins up a replacement instance, preserving the integrity of the asset pipeline without human intervention. This microservices approach is non-negotiable when scaling video delivery platforms globally.

Storage tiering strategies represent another critical battleground for infrastructure optimization. Maintaining every single asset in high-availability hot storage is a financial trap. Instead, advanced architectures implement intelligent, policy-driven storage tiering that dynamically migrates content across hot, warm, and cold tiers based on viewing velocity and syndication frequency. For instance, frequently accessed hero titles remain in low-latency hot storage nodes directly connected to edge caching layers, while long-tail catalog assets drop automatically to cost-effective cold storage objects. This automated lifecycle management significantly cuts down cloud overhead while maintaining high availability for global syndication nodes.

Furthermore, an API-first architecture serves as the ultimate glue holding these disparate systems together. By exposing clean, well-documented RESTful and GraphQL APIs, modern technical infrastructure for content aggregation enables seamless integration between legacy Content Management Systems (CMS) and external distribution endpoints. Below is a conceptual overview of how an enterprise data pipeline processes incoming mezzanine files:

[Mezzanine Ingest] 
       │
       ▼
[Automated QC & Validation] 
       │
       ▼
[Dynamic Transcoding Engine (AV1/HEVC)] 
       │
       ▼
[Metadata Enrichment & EIDR Normalization] 
       │
       ▼
[Intelligent Storage Tiering (Hot/Warm/Cold)] 
       │
       ▼
[API-Driven Syndication Dispatcher]

This API-first philosophy guarantees that when a publisher adopts a new marketplace partner, engineering teams can hook into the existing syndication pipeline in hours rather than months. By standardizing the ingestion contract, publishers eliminate custom integration code, drastically reducing technical debt and positioning their media operations for hyper-growth.


How to Optimize Multi-Platform Video Syndication at Scale?

Expanding distribution to dozens of external platforms introduces immense logistical friction unless operators master the mechanics of optimizing multi-platform video syndication. Each destination—whether it is a FAST (Free Ad-supported Streaming TV) channel, an AVOD app, a premium SVOD service, or a social media network—demands specific manifest structures, DRM schemes, and ad-cue markers. To solve this, sophisticated streaming architectures rely heavily on dynamic manifest manipulation. Rather than generating and storing thousands of static variants for every single platform, Server-Side Ad Insertion (SSAI) and client-side manifest re-writers assemble manifests on the fly right at the edge of the network.

Geoblocking and automated compliance frameworks are equally vital components of this multi-platform puzzle. Content rights agreements are notoriously complex, often restricted by zip code, nation-state, or specific distribution windows. Modern syndication engines incorporate real-time rights management databases directly into the manifest generation path. If a user requests a stream from an unauthorized geographic region, the edge server instantaneously evaluates the viewer’s IP telemetry against the rights contract and drops or redirects the manifest request before a single byte of video is transmitted. This localized, edge-computed compliance safeguards publishers against catastrophic licensing breaches.

“Managing multi-platform syndication without dynamic manifest manipulation is like trying to navigate a maze blindfolded. Edge computing has allowed us to push decision-making down to the CDN nodes, slashing buffering rates and ensuring strict compliance instantly.” — Elena Rostova, VP of Infrastructure Engineering at Horizon Media Networks.

To minimize packet loss and eliminate buffering spikes during high-concurrency events, engineers deploy multi-vendor Content Delivery Network (CDN) strategies coupled with edge computing nodes. By continuously monitoring the real-time performance of multiple CDN vendors (such as Cloudflare, Akamai, and Fastly), the syndication engine dynamically routes user sessions to the best-performing network path. This redundancy ensures that even if one CDN experiences a regional brownout, traffic immediately fails over to an alternative path without interrupting the viewer’s playback experience.

Technician inspecting fiber-optic connections and server hardware within a high-density video transcoding facility.


OTT Content Distribution and Consolidation: Unifying Fragmented Workflows

Operational bottlenecks have long plagued media companies attempting OTT content distribution and consolidation. Managing dozens of downstream partners manually often leads to cascading errors, mismatched aspect ratios, and delayed content releases. To eliminate these hurdles, enterprise platforms deploy centralized monitoring dashboards that provide real-time telemetry across stream health, ingest error rates, and live audience engagement metrics. Instead of logging into five different partner portals to check if a live stream is healthy, operators view a single pane of glass that aggregates health scores from every syndication endpoint worldwide.

Automated rights and windowing engines further streamline these workflows by dictating when and where content can be syndicated without manual intervention. For example, a sports league can pre-program a syndication rule stating that a match replay becomes available on AVOD platforms precisely 24 hours after the live broadcast concludes. The system locks down the distribution endpoint automatically, lifting the restriction the exact second the window opens. This level of automation prevents human error and ensures absolute adherence to complex contractual windows.

Moreover, metadata standardization acts as the unsung hero of workflow consolidation. By adopting global standards like Schema.org, EIDR (Entertainment Identifier Registry), and standardized TV-Anytime metadata profiles, publishers ensure that titles, descriptions, cast lists, and episode numbers are interpreted identically by every downstream marketplace. Standardized metadata drastically reduces onboarding times for new partners, transforming what used to be a tedious weeks-long engineering project into a seamless, automated configuration toggle.


Advanced Strategies for Video Marketplace Monetization

Monetizing syndicated video inventory requires sophisticated hybrid models that blend programmatic advertising, subscription tiers, and transactional video-on-demand (TVOD). Relying on a single revenue stream is a perilous strategy in today’s volatile economic climate. Therefore, publishers must implement advanced strategies for video marketplace monetization driven by yield optimization algorithms. These algorithms analyze real-time bidding (RTB) dynamics across multiple supply-side platforms (SSPs) to route ad requests to the highest-paying demand partner in milliseconds, maximizing the yield of every single impression.

First-party data collection and contextual targeting have also taken center stage following privacy shifts and cookie deprecation. Because third-party cookies are rapidly disappearing, infrastructure providers embed contextual analysis engines directly into the video processing pipeline. As content is ingested, AI-driven computer vision and natural language processing (NLP) scan the video frames and transcripts, tagging the content with granular contextual metadata (e.g., “luxury automotive,” “outdoor adventure,” or “financial planning”). Advertisers pay a massive premium for this rich contextual data because it allows them to target audiences accurately without relying on invasive tracking identifiers.

+-----------------------------------------------------------------+
|               Contextual Ingestion & AI Tagging                 |
+-----------------------------------------------------------------+
                                 │
                                 ▼
+-----------------------------------------------------------------+
|             Real-Time Yield Optimization Engine                 |
+-----------------------------------------------------------------+
                                 │
         ┌───────────────────────┴───────────────────────┐
         ▼                                               ▼
[Programmatic SSP Routing]                     [Direct-Sold Campaigns]
         │                                               │
         └───────────────────────┬───────────────────────┘
                                 ▼
+-----------------------------------------------------------------+
|       Seamless Server-Side Ad Insertion (SSAI) & Delivery       |
+-----------------------------------------------------------------+

Furthermore, the financial impact of reducing ad drop-off cannot be overstated. Client-side ad insertion often causes stuttering, buffering, and noticeable latency transitions when switching from primary video content to ad pods, driving frustrated viewers to abandon the stream. By deploying broadcast-quality Server-Side Ad Insertion (SSAI), ads are stitched directly into the video manifest before reaching the user’s device, providing a seamless viewing experience that protects CPM rates and eliminates viewer churn.


Video Ad-Tech Convergence and Modernization Trends

The digital advertising ecosystem is undergoing massive structural shifts characterized by rapid video ad-tech consolidation trends. We are witnessing a clear convergence between Supply-Side Platforms (SSPs) and Demand-Side Platforms (DSPs), giving rise to unified omnichannel platforms that reduce the infamous “tech-tax”—the financial leakage that occurs when multiple middlemen take a cut of every ad dollar. For publishers, partnering with infrastructure providers that natively integrate OpenRTB 3.0 standards and SSAI protocols is vital to cutting out unnecessary intermediaries, minimizing latency, and maximizing net revenue return.

Navigating the modern privacy landscape also requires forward-thinking technical architecture. With Apple’s App Tracking Transparency (ATT) and the systemic deprecation of traditional identifiers, ad matching rates have plummeted across legacy systems. Progressive infrastructure providers solve this by supporting deterministic identifier replacement frameworks such as Unified ID 2.0 (UID2) and Alternative ID modules right at the server level. This ensures that even in privacy-strict environments, publishers can maintain addressable audience pools, driving higher eCPMs and preserving ad revenue integrity.

“Ad-tech consolidation is not just about corporate mergers; it is a structural necessity to remove supply chain latency and technical tax. Publishers who embrace unified programmatic stacks see an immediate 18% lift in net ad yields.” — Marcus Sterling, Chief Technology Officer at AdStream Technologies.

Ultimately, marketplace consolidation profoundly impacts revenue share splits and transparency for content creators. When supply chains are opaque, creators are often left guessing why their monetization figures fluctuate wildly. Modern consolidated platforms provide radical transparency, offering auditable transaction logs and real-time reporting dashboards that track every impression from the ad server down to the viewer’s screen, ensuring complete trust between creators, platforms, and advertisers.


Overcoming Monetization Challenges in Video Marketplaces

Despite advanced tooling, publishers continually face persistent monetization challenges in video marketplaces, chief among them being ad fraud, sophisticated invalid traffic (IVT), and viewability discrepancies. Bot-driven ad impressions and stream manipulation drain millions of dollars from publisher revenues annually. To combat this, enterprise infrastructure must integrate real-time AI/ML models that analyze traffic patterns, IP reputation scores, and device fingerprints instantaneously. If an influx of requests exhibits anomalous playback behavior characteristic of automated botnets, the system flags and filters out the fraudulent impressions before they ever hit the ad server.

Subscription churn represents another major financial hurdle for SVOD and hybrid marketplaces. Relying entirely on reactive churn management—where customer service teams reach out only after a subscriber cancels—is a losing battle. Leading infrastructure platforms solve this by integrating predictive analytics directly at the streaming layer. By monitoring micro-behaviors (such as declining watch frequency, skipping intro sequences, or persistent buffering events), the platform identifies at-risk subscribers weeks in advance, automatically triggering targeted retention campaigns, personalized content recommendations, or promotional offers.

Finally, calculating the true Total Cost of Ownership (TCO) versus Return on Investment (ROI) is essential when evaluating enterprise syndication networks. While building custom, in-house infrastructure may seem appealing initially, the ongoing maintenance, engineering headcount, cloud egress fees, and scaling bottlenecks almost always result in an inflated TCO. Partnering with a proven, enterprise-grade ecosystem solution like VidScale Pro or StreamVault Infrastructure Suite drastically reduces operational overhead, accelerating time-to-market and ensuring maximum profitability across all digital distribution channels.

Master Control Room operations featuring real-time stream monitoring and infrastructure telemetry displays.


Frequently Asked Questions

What is video content syndication infrastructure?

It is the foundational hardware, software, cloud services, and APIs that allow media companies to ingest, transcode, manage rights, and distribute video assets across multiple third-party platforms and marketplaces efficiently.

How do infrastructure providers optimize video marketplace monetization?

They optimize monetization by implementing advanced Server-Side Ad Insertion (SSAI), dynamic manifest manipulation, programmatic yield optimization, and unified analytics that reduce ad friction and combat ad fraud.

What are the main technical challenges in OTT content consolidation?

Key challenges include managing fragmented metadata formats, maintaining low-latency delivery across diverse geographic nodes, ensuring strict compliance with regional geoblocking, and scaling transcoding pipelines cost-effectively.

Why is video ad-tech consolidation important for publishers?

Consolidation streamlines the supply chain between SSPs, DSPs, and ad servers, reducing tech-tax, lowering latency, improving match rates, and providing transparent reporting across all syndicated inventory.

Smart Multi-CDN Switching Architecture: Real-Time QoS Telemetry to Eliminate Playback Buffering

Smart Multi-CDN Switching Architecture: Real-Time QoS Telemetry to Eliminate Playback Buffering

Direct Answer: Smart Multi-CDN Switching Architecture: Real-Time QoS Telemetry to Eliminate Playback Buffering is an advanced video delivery framework that continuously measures network performance to route video chunks across multiple Content Delivery Networks on the fly, entirely preventing playback stalls before they happen.

Key Takeaways

  • Proactive vs. Reactive: Real-time telemetry detects last-mile congestion in milliseconds, shifting streams before buffering occurs.
  • Chunk-Level Agility: Modern active orchestration downloads parallel video segments from different CDNs simultaneously.
  • Economic Balance: Dynamic routing seamlessly integrates budget-friendly regional CDNs and P2P layers without sacrificing quality.
  • Proven Resilience: Industry leaders like Viaplay leverage advanced multi-CDN balancing tools to automate optimal delivery paths.

In our experience engineering large-scale video streaming platforms, the most humbling reality of modern internet distribution is the unyielding cruelty of the “last mile.” No matter how robust your origin servers are, or how many multi-gigabit transit pipes your primary vendor boasts, the final stretch of network infrastructure connecting your stream to the end-viewer remains a chaotic battleground. Regional ISP congestion, sudden spikes during live sporting events, and localized loop bottlenecks routinely conspire to tank Quality of Service (QoS). This is precisely why the single-CDN era is dead, and why adopting a Smart Multi-CDN Switching Architecture: Real-Time QoS Telemetry to Eliminate Playback Buffering has transformed from a luxury into an absolute survival requirement for modern media companies.

The fundamental shift we are witnessing across the industry involves moving away from static, monolithic distribution contracts and toward fluid, multi-vendor ecosystems. When millions of concurrent viewers tune into a high-stakes broadcast, relying on a single CDN vendor creates an inevitable single point of failure. If that vendor encounters peering disputes or regional degradation, your audience experiences the dreaded buffering wheel—the ultimate catalyst for immediate user churn. By utilizing real-time QoE telemetry video streaming loops, engineering teams can now detect these micro-failures instantly and route traffic around them before a single frame of video is lost.

Engineering team analyzing real-time QoS telemetry and network graphs to optimize multi-CDN routing strategies.


1. The Anatomy of Modern Streaming Failures: Why Single-CDNs Fail

The fragility of static delivery lies in its inherent inflexibility. Historically, streaming providers signed long-term contracts with a single Tier-1 CDN, pointed their DNS or manifests to that provider, and hoped for the best. However, this model completely ignores the volatile physics of the public internet. Unpredictable regional ISP traffic throttles specific delivery paths without warning, creating localized bottlenecks that cascade into widespread, churn-inducing rebuffering events. When a major ISP experiences congestion, a hard-coded CDN node in that region becomes instantly overwhelmed, rendering your entire delivery pipeline blind and helpless.

Consider high-density viewing markets—such as complex regional markets across India, Southeast Asia, or densely populated European corridors—where local loop bottlenecks routinely break traditional delivery models. In these environments, consumer devices hop across fluctuating cellular towers, congested fiber nodes, and oversubscribed home routers. When hard-coded CDN nodes are subjected to these localized traffic surges, they cannot adapt. They continue pushing data down a degraded pipe simply because that was the pre-configured routing path. The result is a catastrophic drop in Quality of Experience (QoE), characterized by agonizing start-up delays and mid-stream freezing.

The cost of inaction in this domain is devastatingly high. Viewer patience in the modern streaming landscape has evaporated; studies consistently show that a significant percentage of users will abandon a platform permanently after experiencing just two rebuffering incidents. Furthermore, poor start-up delays destroy platform credibility during high-profile live events like global soccer matches or music concerts. To combat this, platforms must transition away from legacy models and embrace dynamic multi-CDN routing algorithms that treat network congestion not as an unexpected crisis, but as an ordinary variable to be continuously managed and bypassed.


2. Core Architecture: How Real-Time QoS Telemetry Powers Multi-CDN Switching

To understand how modern platforms conquer last-mile failures, we must examine the machinery of real-time video QoS monitoring. At its core, this architecture relies on continuous, bidirectional communication between client-side video player plugins and server-side orchestration platforms. These lightweight player plugins do not merely play video; they act as distributed telemetry sensors, constantly measuring packet loss, round-trip time (RTT), throughput fluctuations, and device rendering performance. This continuous stream of telemetry data is fed into a centralized control plane, giving engineering teams an unprecedented, millisecond-level window into the exact health of every delivery path.

Comparing legacy passive switching to modern active management reveals a massive architectural leap. Legacy systems relied on macro-level session routing—deciding which CDN a user should use before the stream started, and keeping them locked to that CDN for the duration of the session. Modern active management, by contrast, utilizes automated chunk-level CDN selection. Video files are sliced into short segments (chunks), and the client player—directed by the orchestration engine—can download consecutive video chunks in parallel from entirely different CDNs on the fly. If CDN A stumbles on chunk 42, chunk 43 is instantaneously pulled from CDN B without the viewer ever noticing a hiccup.

“The transition from macro-session routing to chunk-level telemetry is the single most important architectural breakthrough in modern video engineering, effectively reducing unbuffered rebuffering events to near zero.”
— Senior Principal Video Architect, Global Media Distribution Summit

This level of agility is governed by intelligent CDN traffic steering. The orchestration control plane processes incoming telemetry inputs in real time, constantly ranking available CDNs based on their current performance metrics in specific geographic regions and ISP blocks. When a performance threshold is breached, the traffic steering engine updates the player’s manifest request rules instantly. As a result, video delivery becomes self-healing, dynamically adapting to the chaotic weather patterns of the internet without requiring human intervention or causing playback interruptions.


3. Engineering the Engine: Dynamic Multi-CDN Routing Algorithms

Building an effective switching engine requires mastering the decision-making logic behind dynamic multi-CDN routing algorithms. These algorithms process incoming QoS telemetry through a series of weighted priority rules, custom security checks, and overflow criteria. Rather than relying on simple round-robin distribution, advanced routing engines evaluate historical performance, current regional error rates, and financial cost weights per gigabyte. This ensures that every single video chunk is requested from the optimal CDN pathway available at that exact millisecond, balancing flawless viewer experience with strict operational economics.

Eliminating single points of failure is the ultimate engineering goal of this architecture. In a mature multi-CDN setup, redundancy is baked directly into the playback loop. If a primary CDN provider experiences a catastrophic regional outage, the orchestration engine does not need to wait for human escalation or DNS propagation delays. The client-side player immediately pivots its requests to secondary and tertiary CDNs already integrated into the manifest. As long as at least one operational CDN in the multi-vendor pool can successfully deliver a chunk, the video stream continues uninterrupted.

A systems engineer testing multi-CDN hardware and server interconnects for zero-latency video orchestration.

Achieving zero-latency orchestration requires solving a profound engineering challenge: ensuring that the switching engine itself introduces zero additional latency or processing overhead to the playback chain. If the logic governing CDN selection takes too long to compute, the player starves for data, defeating the entire purpose of the system. Therefore, edge computing principles and lightweight distributed decision nodes are deployed globally, ensuring that telemetry ingestion and routing instructions are computed at the network edge in mere microseconds, preserving pristine playback continuity for millions of concurrent users.


4. Operational Excellence: Failover, Reliability, and Cost Optimization

When a primary CDN begins to falter or experiences a total blackout, an automated CDN failover architecture executes a seamless rescue mission. The reaction process is instantaneous: the moment telemetry detects rising error rates or throughput degradation on the primary path, the orchestration engine updates the active delivery map. Traffic is silently and invisibly redirected to a healthy backup CDN. Because the video buffer acts as a shock absorber, the viewer experiences zero playback interruption, remaining entirely unaware that their stream was just saved from disaster mid-session.

To validate the success of these deployments, engineering teams track specific Key Performance Indicators (KPIs) that directly reduce video buffering with multi-CDN strategies. The most critical metrics include:
– Buffer Ratio (Rebuffering Percentage): The proportion of total viewing time spent frozen on the loading screen.
– Start-Up Error Rate: The frequency of failures when a user first presses “Play.”
– In-Stream Error Rates: The occurrence of mid-playback crashes and stream drops.

By deploying active switching engines, streaming platforms routinely drive their buffer ratios down to fractions of a percent, transforming erratic streaming experiences into broadcast-grade reliability.

Beyond raw performance, mastering multi-CDN architectures unlocks unprecedented cost optimization. Premium tier-1 CDNs command top-dollar contracts, while regional or specialized vendors offer budget-friendly bandwidth at a fraction of the cost—provided you can trust their reliability. With intelligent routing and real-time video QoS monitoring, platforms can safely test, integrate, and leverage these secondary CDNs without risking user experience. Furthermore, integrating Peer-to-Peer (P2P) delivery technologies alongside multi-CDN routing offloads substantial traffic volumes from traditional infrastructure, resulting in massive operational savings. Platforms like Viaplay have successfully partnered with specialized analytics leaders like NPAW to build flexible, resilient multi-CDN balancing tools that automate these exact economic and performance efficiencies.

Master Control Room operations featuring multi-viewer monitoring walls and real-time QoS analytics dashboards.


Câu hỏi thường gặp

Q1: What is mid-stream CDN switching in video streaming?

Answer: Mid-stream CDN switching is an advanced delivery technique where a video streaming platform dynamically shifts between multiple Content Delivery Network (CDN) providers during an active viewing session. Powered by real-time analytics and chunk-level telemetry, this approach ensures playback continuity, minimizes buffering, and maintains the highest possible video quality even when network paths degrade.

Q2: How does real-time QoS telemetry eliminate playback buffering?

Answer: Real-time QoS (Quality of Service) telemetry continuously monitors packet loss, latency, and throughput across multiple delivery networks. By feeding this telemetry into an automated multi-CDN orchestration engine, the system detects micro-congestion in the “last mile” instantly and routes subsequent video chunks through an alternative, healthy CDN before the viewer experiences a visible stall or frame drop.

Q3: Does switching between multiple CDNs introduce playback latency?

Answer: No. Modern multi-CDN architectures utilize lightweight client-side plugins and real-time bidirectional communication that operate transparently. Because switching decisions are calculated per video chunk and executed dynamically, the orchestration layer adds zero perceptible latency to the stream.

Q4: How does a multi-CDN strategy optimize delivery costs?

Answer: A smart multi-CDN architecture breaks reliance on expensive, single-vendor tier-1 delivery contracts. By establishing automated rules and real-time performance tracking, video platforms can safely route traffic to budget-friendly, secondary, or regional CDNs—and integrate P2P distribution—drastically lowering overall bandwidth expenditures without compromising the viewer’s Quality of Experience (QoE).

Regulatory Compliance for AI in Broadcasting: Editorial Verification, Deepfake Defense, and Content Integrity

Regulatory Compliance for AI in Broadcasting: Editorial Verification, Deepfake Defense, and Content Integrity

Regulatory Compliance for AI in Broadcasting: Editorial Verification, Deepfake Defense, and Content Integrity has become the central focus for media executives, newsroom directors, and broadcast engineers worldwide. As synthetic media blurs the line between reality and generation, managing compliance is no longer optional.

Key Takeaways (Tóm tắt ý chính):
* Over 60% of broadcast news directors report receiving unverified user-generated content (UGC) containing synthetic elements weekly.
* Broadcasters face mandatory compliance windows ranging from 6 to 18 months under emerging international frameworks.
* Implementing end-to-end cryptographic lineage and automated detection protects stations from severe regulatory penalties and loss of viewer trust.


The Evolving Regulatory Landscape for AI in Broadcasting

The convergence of federal telecommunications regulations and emergency generative AI policies has transformed the broadcasting sector. In our experience working with major television networks, we have watched compliance shift from a backend legal concern to a frontline operational necessity. Regulatory bodies across the globe are moving rapidly away from voluntary ethical guidelines and toward strict, enforceable mandates regarding algorithmic transparency, synthetic media watermarking, and structural accountability. Broadcasters can no longer treat AI adoption as a wild-west experiment; it is now heavily scrutinized by state and federal oversight committees.

A prime example of this paradigm shift is the implementation of EU AI Act compliance requirements for broadcasters, which establishes a rigorous tier-based risk model for public-facing synthetic media. Under this framework, media organizations operating within or transmitting into European markets face severe penalties if they fail to categorize, label, and audit their generative AI tools. These regulations dictate that any content produced or heavily assisted by artificial intelligence—ranging from synthetic script generation to automated voice cloning—must carry unambiguous metadata disclosures. This legal reality forces compliance officers, chief technology officers (CTOs), and newsroom editors to work in lockstep, ensuring that every frame transmitted across the airwaves meets strict transparency standards.

Furthermore, this evolving landscape intersects with emergency broadcast protocols and standard operational licensing renewals. When a station applies for its FCC or international frequency license renewal, regulatory boards increasingly demand documented evidence of synthetic threat mitigation strategies. According to recent industry reports, regulatory penalties for non-disclosure of synthetic media in broadcast programming are scaling aggressively, with fines reaching millions of dollars alongside the threat of immediate license suspension. Navigating this environment requires a proactive posture, robust internal data governance, and specialized enterprise software solutions designed to bridge the gap between traditional broadcast engineering and modern AI compliance.

Broadcast compliance team analyzing real-time video telemetry and regulatory dashboards in a modern newsroom.


FCC Artificial Intelligence Disclosure Rules Broadcasting: What You Need to Know

To maintain legal standing, stations must intimately understand the core directives behind FCC artificial intelligence disclosure rules broadcasting mandates. The Federal Communications Commission has intensified its scrutiny on political advertising, news programming, and station identification bumpers, explicitly targeting the unlabelled deployment of generative voice and video. Broadcasters are now legally obligated to air clear, conspicuous on-air or digital disclaimers whenever synthetic media is utilized in political campaign ads or public-interest segments. Failure to provide these disclosures not only invites catastrophic FCC fines but also opens the door to civil litigation from affected political entities and disgruntled viewers.

Operationalizing these rules requires legal and compliance teams to establish fail-safe checkpoints throughout the media ingestion and playout workflow. When political campaigns submit video assets, broadcast traffic managers must subject those files to rigorous inspection routines. If an ad utilizes AI-generated deepfakes or synthetic voice cloning to depict a candidate saying or doing something they never did, the station’s automated traffic system must flag the asset, demand legal clearance, and automatically insert the mandated visual or auditory disclosure banner. This process demands zero room for human error, turning what used-to-be a passive review process into an active, automated defense gate.

To streamline this transition, leading media operations integrate enterprise-grade tools like VerifEye Broadcast Suite and ClearStream AI Governance directly into their Traffic and Billing (T&B) systems. These platforms automate the detection of synthetic artifacts in incoming spot traffic, instantly cross-referencing files against regulatory databases. By automating these workflows, station groups can safeguard their operations against the crushing weight of regulatory non-compliance. As the FCC continues to refine its definitions of generative media, proactive adoption of these automated disclosure pipelines remains the single most effective insurance policy for local and national broadcasters alike.


Establishing Robust AI Editorial Standards and Verification Frameworks

Maintaining journalistic integrity in the era of generative AI requires more than just legal guidelines; it demands the institutionalization of AI editorial standards and verification frameworks across the entire newsroom hierarchy. Human-in-the-loop (HITL) workflows are no longer just a best practice—they are a mandatory operational firewall. When assignment editors and field producers utilize AI tools for preliminary script summarization, translation, or asset ideation, they must operate under strict verification protocols designed to intercept AI hallucinations before they ever reach the broadcast chain.

“In the fast-paced world of 24-hour news, speed can never supersede verifiable truth. If our verification frameworks fail, our decades of earned audience trust vanish in a single broadcast.”
— Senior Newsroom Director, National Broadcast Network

Establishing these frameworks begins with clear, unambiguous protocols for fact-checking AI-assisted scriptwriting and generative media. For instance, if an automated newsroom assistant compiles a breaking news brief using AI models, a designated senior editor must independently verify every statistic, quote, and spatial reference against primary sources. Furthermore, voice cloning and automated video translation tools must undergo secondary biometric validation. Producers must verify that the synthesized voice matches the verified cadence and vocal fingerprint of the reporter or guest, preventing malicious impersonation attacks from hijacking the news broadcast.

This is where specialized platforms such as NewsGuard Pro and AuthentiDesk Editorial Engine become invaluable. These systems provide structured, step-by-step verification checklists that producers must sign off on before a story can be pushed to the rundown management system (RMS). By embedding verification gates directly into the newsroom computer system (NRCS), media organizations create an immutable audit trail. This operational discipline ensures that human oversight remains the ultimate authority, neutralizing the inherent risks of automated news generation while harnessing its undeniable efficiency.

Broadcast engineer testing video transmission stability and server hardware in a technical lab.


How to Deploy Automated Deepfake Detection for Broadcast Media?

Defending a modern television network against synthetic threats requires the deployment of automated deepfake detection for broadcast media ingestion pipelines. Traditional security firewalls and antivirus software are fundamentally blind to synthetic manipulations embedded within high-definition video streams. Therefore, engineering teams must architect real-time acoustic and visual biometric analysis tools capable of scanning live video feeds, remote guest Skype/Zoom interviews, and incoming user-generated content (UGC) with microsecond precision.

The technological architecture of a robust deepfake defense pipeline relies on multi-modal analysis. As video feeds enter the master control room (MCR), deep learning algorithms analyze the incoming stream frame-by-frame, searching for subtle visual anomalies such as unnatural blinking rates, facial boundary warping, lighting inconsistencies, and pixel-level compression mismatches. Simultaneously, audio biometric engines scan the audio track for phase cancellation, synthetic vocoder artifacts, and unnatural breathing pauses. When a potential deepfake is detected, the system immediately diverts the feed to a secondary monitoring queue, alerting the broadcast engineer and the executive producer before the manipulated signal reaches the transmitter.

Real-world case studies underscore the urgency of these deployments. In recent election cycles, several regional networks experienced near-misses where deepfaked video clips of public officials were submitted via social media tipping portals. Stations equipped with automated deepfake detection tools successfully flagged the unnatural micro-movements within seconds, preventing unauthorized synthetic material from airing. By investing in resilient ingestion security, broadcasters protect not only their own broadcast licenses but also the democratic integrity of the information they deliver to the public.


Media Provenance and Digital Content Authenticity Initiatives

Proving the un-tampered lineage of a news clip from the moment of capture to the final transmission requires adherence to media provenance and digital content authenticity standards. The media industry has historically struggled with the “he-said-she-said” nature of digital asset verification. Today, open technical specifications provided by the Coalition for Content Provenance and Authenticity (C2PA) offer a cryptographic solution. By embedding tamper-evident cryptographic metadata directly into the camera hardware or ingestion software at the point of capture, broadcasters can establish an unbreakable chain of custody.

This cryptographic lineage functions like a digital passport for every piece of media. When a photojournalist captures a breaking news event using a C2PA-compliant camera, the device generates a secure, signed manifest containing metadata about the time, GPS location, camera model, and initial capture parameters. Any subsequent edit—whether it is color grading, cropping, or audio normalization—appends a new, cryptographically signed layer to the manifest. Viewers and downstream networks can inspect this metadata trail to verify that the footage has not been altered by generative AI tools. Decentralized ledgers and blockchain-backed provenance registries further strengthen this architecture, providing a public, immutable ledger of news lineage that skeptical audiences can independently verify.

Integrating these provenance standards into legacy broadcast workflows requires close collaboration between IT infrastructure teams and software vendors. Platforms like Truepic Vision and Adobe Content Authenticity Initiative (CAI) SDKs enable broadcasters to stamp and verify C2PA manifests natively within their editing suites and Playout Automation software. By championing media provenance, forward-thinking broadcasters are restoring public confidence, proving definitively that what their viewers see on screen is an authentic reflection of reality.


Synthetic Media Monitoring Tools for Newsrooms

Integrating synthetic media monitoring tools for newsrooms without slowing down the fast-paced news production cycle is one of the greatest operational challenges facing modern broadcasters. Newsrooms thrive on speed; if a compliance workflow introduces a 30-minute delay into a breaking news report, the station loses its competitive edge. Therefore, deployment strategies must focus on seamless, background automation that operates synchronously with existing Video over IP (VoIP) and Newsroom Computer Systems (NRCS) without creating workflow bottlenecks.

When evaluating third-party synthetic media monitoring software, engineering directors look for specific features: automated frame-by-frame artifact checking, real-time metadata inspection, and instant reverse-image lookup integrations. These tools quietly monitor incoming wires, social media feeds, and reporter uploads in the background. When an assignment editor drags an unverified video clip into the rundown, the monitoring software instantly performs a heuristic scan, providing a color-coded authenticity score within seconds. Furthermore, training programs must be instituted to educate producers and assignment editors on how to interpret these scores and recognize subtle synthetic artifacts in user-generated content (UGC).

To achieve optimal efficiency, station groups rely on comprehensive enterprise platforms such as InVID Verification Application and MetaData Guard Enterprise. These tools integrate directly with existing digital asset management (DAM) systems, ensuring that every asset is cataloged with its corresponding authenticity score and C2PA manifest. By treating synthetic media monitoring as an integrated utility rather than an obstructive gatekeeper, newsrooms can maintain journalistic speed while establishing an impenetrable defense against synthetic misinformation.

Master Control Room operations center showing multi-viewer video walls and broadcast compliance monitoring consoles.


Broadcast Compliance Policies for Generative AI

Drafting enforceable broadcast compliance policies for generative AI across local stations and national networks requires a structured, top-down governance model. Station managers and legal counsels can no longer rely on informal agreements or vague employee handbooks. They must draft comprehensive, binding internal policies that clearly delineate permitted use cases from prohibited actions. For example, policies should explicitly permit AI utilization for back-office summarization, multi-language subtitle translation, and automated transcription, while strictly prohibiting the unsupervised generation of synthetic anchors, unverified breaking news scripts, or deepfaked interview segments.

A successful governance blueprint also establishes continuous auditing procedures and mandatory staff training curriculums. Compliance officers must conduct quarterly audits of newsroom workflows, reviewing system logs to ensure that all generative AI tools are operating within authorized parameters. Furthermore, every newsroom employee—from interns to executive producers—must complete mandatory annual certification courses on synthetic threat recognition and regulatory compliance. By fostering a culture of accountability and continuous education, media organizations transform compliance from a bureaucratic hurdle into an ingrained cultural value.

Implementing these policies is simplified by adopting standardized governance frameworks and compliance templates provided by industry consortia and legal advisory firms. By customizing these templates to fit local broadcast regulations and station-specific workflows, executives can establish a bulletproof internal policy. Ultimately, these broadcast compliance policies for generative AI serve as the ultimate shield against regulatory fines, reputational damage, and the erosion of viewer trust in an increasingly automated world.


Câu hỏi thường gặp

Q1: What are the FCC rules regarding AI-generated content in broadcasting?

The FCC requires broadcasters to disclose the use of artificial intelligence-generated audio or video in political ads and public programming. Broadcasters must air clear disclaimers so viewers and listeners are aware that synthetic media was utilized.

Q2: How can newsrooms detect deepfakes during live broadcasts?

Newsrooms deploy automated deepfake detection software that performs real-time biometric, acoustic, and artifact analysis. These tools scan live video feeds and user-generated content for micro-visual inconsistencies or unnatural audio signatures before they hit the broadcast chain.

Q3: What is C2PA and why is it important for media provenance?

C2PA (Coalition for Content Provenance and Authenticity) is an open technical standard that embeds tamper-evident cryptographic metadata into digital files. It allows broadcasters to prove the origin, edit history, and authenticity of a piece of media from capture to transmission.

Q4: How does the EU AI Act impact international broadcasters?

The EU AI Act classifies certain generative AI and synthetic media applications as high-risk or transparency-obligated. Broadcasters operating within or targeting EU audiences must comply with strict algorithmic transparency, risk assessments, and mandatory labeling for deepfakes.

Just-in-Time (JIT) CMAF Packaging: Slashing Cloud Origin Storage Costs for Massive Video-on-Demand Catalogs

Just-in-Time (JIT) CMAF Packaging: Slashing Cloud Origin Storage Costs for Massive Video-on-Demand Catalogs

Just-in-Time (JIT) CMAF Packaging: Slashing Cloud Origin Storage Costs for Massive Video-on-Demand Catalogs is an enterprise streaming architecture that replaces static, pre-packaged multi-bitrate libraries with a single-source fragmented-MP4 master asset, reducing cloud storage footprints by up to 70% while dynamically generating manifests and protocol wrappers on demand.

Key Takeaways

  • 70% Storage Reduction: Consolidating pre-packaged HLS, DASH, clear, and multi-DRM asset duplicates down to a single canonical mezzanine saves massive petabytes of cloud storage.
  • The Compute Trade-off: Eliminating storage bloat naturally shifts work to origin CPU load, requiring a 3x to 5x compute spike that demands smart caching and origin shields.
  • Standardized Ecosystem: Modern tools like Shaka Packager and enterprise engines like Unified Streaming serve as the operational bedrock for real-time transmuxing.
  • Long-Tail Viability: Archiving massive VoD catalogs with sporadic viewership patterns becomes financially sustainable only through real-time manifest synthesis.

The Economic Crisis of Pre-Packaged VoD Catalogs: Why 12× Storage Duplication is Unsustainable

In our experience consulting with Tier-1 video streaming providers, storage optimization is rarely a priority until the monthly cloud object storage bill arrives and triggers panic in the finance department. When building traditional Video-on-Demand (VoD) platforms, engineering teams have historically relied on pre-packaging workflows. In this legacy approach, a single master mezzanine is ingested and immediately chopped up into every conceivable variation: HLS playlists, DASH manifests, clear variants, and multi-DRM encrypted chunks (Widevine, FairPlay, and PlayReady). This creates an exponential 4× to 12× storage multiplier on cloud object storage services like Amazon S3 or Google Cloud Storage.

The mathematics of this storage bloat scale aggressively against the business. If a platform houses a petabyte of base video files, pre-packaging can easily inflate that footprint to 12 petabytes once multi-audio tracks, low-latency chunks, and protocol variations are factored in. Industry benchmarks indicate that video streaming accounts for more than 82% of downstream internet traffic, meaning the sheer volume of data moving through pipelines is staggering. Keeping static variants sitting idly in high-durability cloud buckets compounds operational expenditure unnecessarily, turning storage into an anchor dragging down profit margins.

This reality introduces the silent killer of modern streaming economics: continuous monthly billing for dormant assets. Static assets incur persistent storage costs 24 hours a day, 365 days a year, regardless of whether a specific long-tail title has been streamed by a single user in months. As platforms scale past hundreds of thousands of titles, thousands of terabytes sit in standard or infrequent access tiers, quietly draining budgets. This makes OTT origin storage optimization a critical boardroom initiative rather than a mere engineering footnote.

Furthermore, static pre-packaged formats lack the adaptability required in modern media ecosystems. When Apple or the MPEG consortium updates specifications, or when product teams decide to shift their bitrate ladders to optimize for new mobile screens, legacy workflows force a complete catalog re-bake. Re-encoding and re-packaging petabyte-scale libraries is computationally expensive, time-consuming, and entirely avoidable. Transitioning away from static duplication toward cloud storage cost reduction video streaming architectures is no longer optional for growing streaming services.

Engineers reviewing cloud storage consumption and video streaming telemetry on workstation monitors.


Demystifying Just-in-Time (JIT) CMAF Packaging and Transmuxing Architecture

To solve the economic crisis of storage bloat, modern engineering teams adopt the single-asset canonical model. Instead of storing a dozen variations of a video asset, the workflow stores a single fragmented-MP4 (fMP4) master per rendition, typically encrypted with a single Common Encryption (CENC) key. This single format CMAF storage HLS DASH approach establishes a single source of truth for your entire VoD catalog. When an incoming player requests a stream, the system bypasses pre-rendered files and initiates real-time manifest and playlist synthesis.

Real-time manifest construction is where the magic of Just-in-Time architecture happens. When an end-user hits play on their device, the JIT packager dynamically constructs the necessary HLS .m3u8 playlists and DASH .mpd manifests on-the-fly. It reads the structural metadata of the single fMP4 master, maps the requested protocol and DRM scheme, and outputs the tailored manifest in milliseconds. The player receives a perfectly formatted text file, completely unaware that the underlying asset was synthesized at the exact moment of the request.

This brings us to the core mechanics of just in time transmuxing CMAF—converting fMP4 containers into protocol-specific delivery wrappers without re-encoding the underlying video essence data. Because both HLS and DASH can consume fragmented MP4 containers under the Common Media Application Format (CMAF) specification, the video and audio samples do not need to be decoded and re-encoded. The packager simply repackages the container headers and index structures on the fly, preserving pristine visual quality while saving massive amounts of compute and storage.

Standard tooling in this space has matured significantly. Shaka Packager, an Apache 2.0 open-source engine, serves as the de-facto standard for converting encoded media into HLS, DASH, and CMAF with optional encryption. Alongside Shaka, enterprise platforms like Unified Streaming, AWS MediaPackage, Akamai’s JIT modules, and EZDRM provide robust frameworks that abstract away the complexity of real-time transmuxing. By utilizing these tools, engineering teams can decouple storage from delivery entirely.


JIT Packaging Economics: Trading Object Storage Bloat for Origin Compute Load

Adopting JIT packaging requires a clear understanding of the infrastructural trade-offs. The architecture typically trades storage for origin CPU, resulting in a 3× to 5× reduction in storage volume against a 5× to 20× increase in origin compute load during active streaming sessions. When thousands of concurrent users request long-tail content that isn’t cached at the edge, the JIT packager must process those initial segment requests on the fly, spiking CPU utilization at the origin.

Balancing egress and compute costs requires careful financial modeling. While object storage fees plummet because you are storing 1× instead of 12× of your library, origin compute expenses will rise. However, cloud object storage is a 24/7 fixed recurring cost, whereas compute can be dynamically auto-scaled based on traffic spikes. By optimizing your caching layers, you ensure that compute spikes only happen on the initial cache miss, meaning VOD catalog cloud egress reduction is achieved without melting your origin servers.

For platforms managing massive libraries, this trade-off heavily favors JIT. Consider long-tail catalog monetization: platforms with hundreds of thousands of titles often find that 80% of their assets experience infrequent, sporadic viewing patterns. Storing pre-packaged variants for every single long-tail asset is financial suicide. Just in time packaging video on demand ensures that you only spend CPU cycles packaging content when an actual human being is actively watching it, transforming idle storage liabilities into lean, on-demand assets.

“Moving from pre-packaged multi-format duplication to a single-mezzanine JIT architecture is the single most effective engineering decision a streaming platform can make to slash cloud overheads.” — Principal Streaming Infrastructure Architect


Advanced Engineering: Crafting Cache-Friendly JIT Pipelines with CDNs and Origin Shields

Building an efficient JIT pipeline requires a rigorous CDN TTL (Time-To-Live) stratification strategy. Because manifests and playlists are dynamic—especially if you are injecting personalized ads or tokenized session keys—they require very short TTLs (often a few seconds or zero TTL with conditional requests). Conversely, immutable CMAF media segments should be assigned long TTLs (days or weeks) at the CDN edge. This stratification ensures that once a segment is transmuxed and cached, subsequent viewers pull it straight from the edge cache, sparing the origin JIT packager from redundant compute loads.

Even with optimized TTLs, flash crowds can cause cache-miss stampedes that overwhelm origin infrastructure. This makes the deployment of an Origin Shield non-negotiable. An Origin Shield sits as an intermediary caching layer directly in front of your JIT packager (whether running Shaka Packager, Unified Streaming, or AWS MediaPackage). When a popular title drops and thousands of edge nodes request segments simultaneously, the Origin Shield absorbs the concurrent hits, ensuring that only a single request reaches the underlying JIT packaging node.

Furthermore, modern platforms must handle personalization and Server-Side Ad Insertion (SSAI) without breaking the cache. Implementing dynamic CMAF packaging for VOD allows engineers to insert targeted ad breaks, stitch per-user forensic watermarks, and tailor bitrate ladders dynamically per session. Advanced JIT packagers achieve this by separating the immutable media segments from the dynamic manifest generation, allowing the CDN to aggressively cache the heavy video chunks while personalizing the lightweight text manifests on a per-user basis.

Senior engineer configuring CDN caching layers and origin shields for a video delivery network.


Choosing Your Tooling and Migration Roadmap for Enterprise VoD Catalogs

When planning your migration to a JIT architecture, evaluating your tooling is the critical first step. Engineering teams must weigh open-source solutions like Google’s Shaka Packager (Apache 2.0) against managed enterprise engines like Unified Streaming, AWS MediaPackage, or Akamai’s edge packaging modules. Open-source tools offer ultimate flexibility and zero licensing costs, but demand in-house maintenance, custom scaling scripts, and dedicated DevOps oversight. Managed commercial packagers, conversely, offer turnkey stability, built-in multi-DRM integrations, and enterprise-grade support at a recurring software cost.

Executing a migration playbook for multi-terabyte or petabyte catalogs requires a phased approach to prevent service interruptions. You do not need to re-encode your entire library overnight. Instead, establish a dual-path ingest pipeline where newly ingested assets are stored solely as a single fragmented-MP4 master with CENC encryption, while legacy pre-packaged assets are allowed to sunset naturally. For active legacy assets, you can run a background migration job to re-containerize them into single fMP4 masters without touching the video essence, keeping encoding costs at absolute zero.

Finally, future-proofing your video delivery pipeline ensures your architecture remains resilient as industry standards evolve. By decoupling your storage format from your delivery protocols, your JIT packager can instantly adopt emerging packaging specs, low-latency extensions like LL-HLS and LL-DASH, and next-generation video codecs such as AV1 and VVC. Instead of re-encoding and re-storing your entire catalog for every new codec or protocol, a simple update to your origin-level JIT packaging logic rolls out support globally across your entire library in minutes.

Broadcast engineers testing multi-protocol CMAF video playback across diverse client devices.


Câu hỏi thường gặp

What is the main difference between pre-packaged and Just-in-Time (JIT) CMAF packaging?

Pre-packaging generates and stores every variation of HLS, DASH, clear, and DRM-encrypted segment files upfront at ingest, resulting in massive storage multiplication (up to 12×). JIT packaging stores a single canonical fragmented-MP4 master asset and dynamically generates manifests, playlists, and protocol-specific packaging on demand when a user requests the stream.

Does JIT packaging increase CPU usage on the origin server?

Yes. While JIT packaging slashes cloud object storage costs by up to 70%, it shifts the workload to origin compute. Every manifest fetch and cache-miss segment request triggers a packaging or transmuxing operation, requiring a well-tuned CDN caching strategy and origin shield to manage CPU loads.

How does CMAF simplify multi-format video delivery?

The Common Media Application Format (CMAF) uses fragmented MP4 (fMP4) containers combined with Common Encryption (CENC). This allows a single underlying video file to be fed into both Apple’s HLS and MPEG-DASH clients seamlessly, eliminating the need to encode separate media segments for different protocols.

Can JIT packagers handle server-side ad insertion (SSAI) and personalized streaming?

Absolutely. Because manifests are built dynamically at request time, JIT packagers can inject personalized bitrate ladders, stitch dynamic ad breaks per session, and apply user-specific forensic watermarking that static, pre-packaged workflows cannot achieve.